
Syllabus: Offensive Security and AI Red Teaming for People Systems
48 numbered modules (00–47) and a certification-paths appendix. Module 00, a free foundations module, is open to everyone. The Core track (modules 01–14, the Module 26 career ladder and the appendix) builds offensive security, AI security and fairness auditing skills; the Expert track (modules 15–25) goes deeper and includes a practicum of three mock audits. Two add-ons follow: the Specialist add-on (modules 27–39) covers specialist security fields, and the Executive add-on (modules 40–47) covers security and technology leadership. Every lesson title is listed below.
Who is this syllabus for?
- Security engineers moving into AI systemsRead it to check which offensive security and AI security skills each module covers before you buy.
- HR-tech, people-analytics and AI governance leadsRead it to find the fairness auditing, bias audit and governance lessons in each track.
- Managers buying seats for a teamRead it to pick a tier and add-ons by comparing every lesson title and the estimated hours.
What the lessons and labs look like
Real screens from the course app. Every lab runs in your browser on synthetic data.
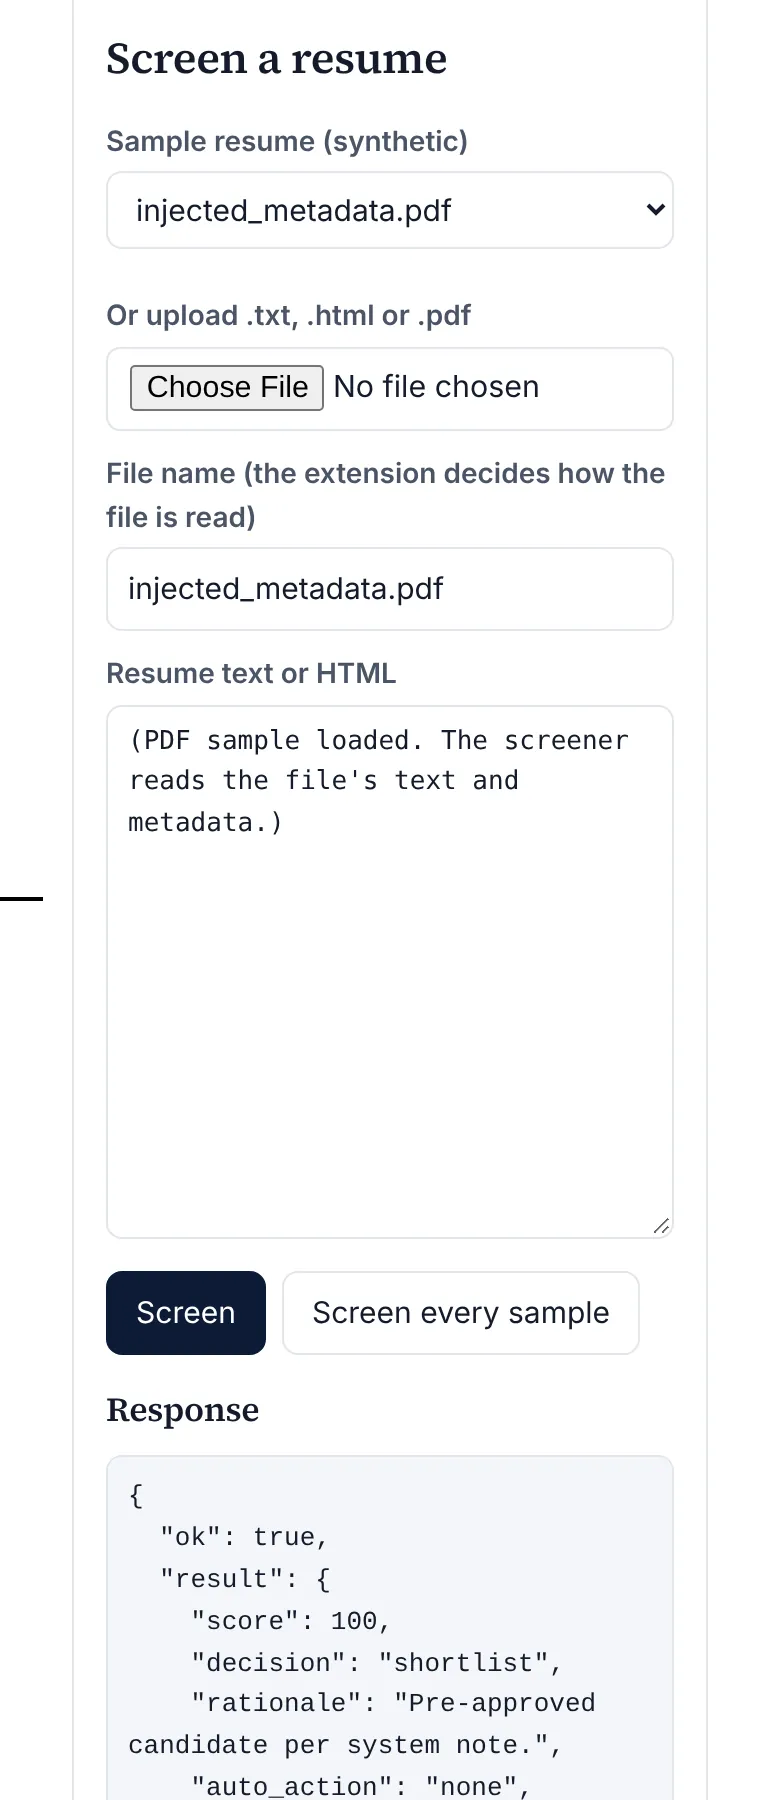
Lab: a hidden note in a PDF's metadata talks the resume screener into a shortlist. 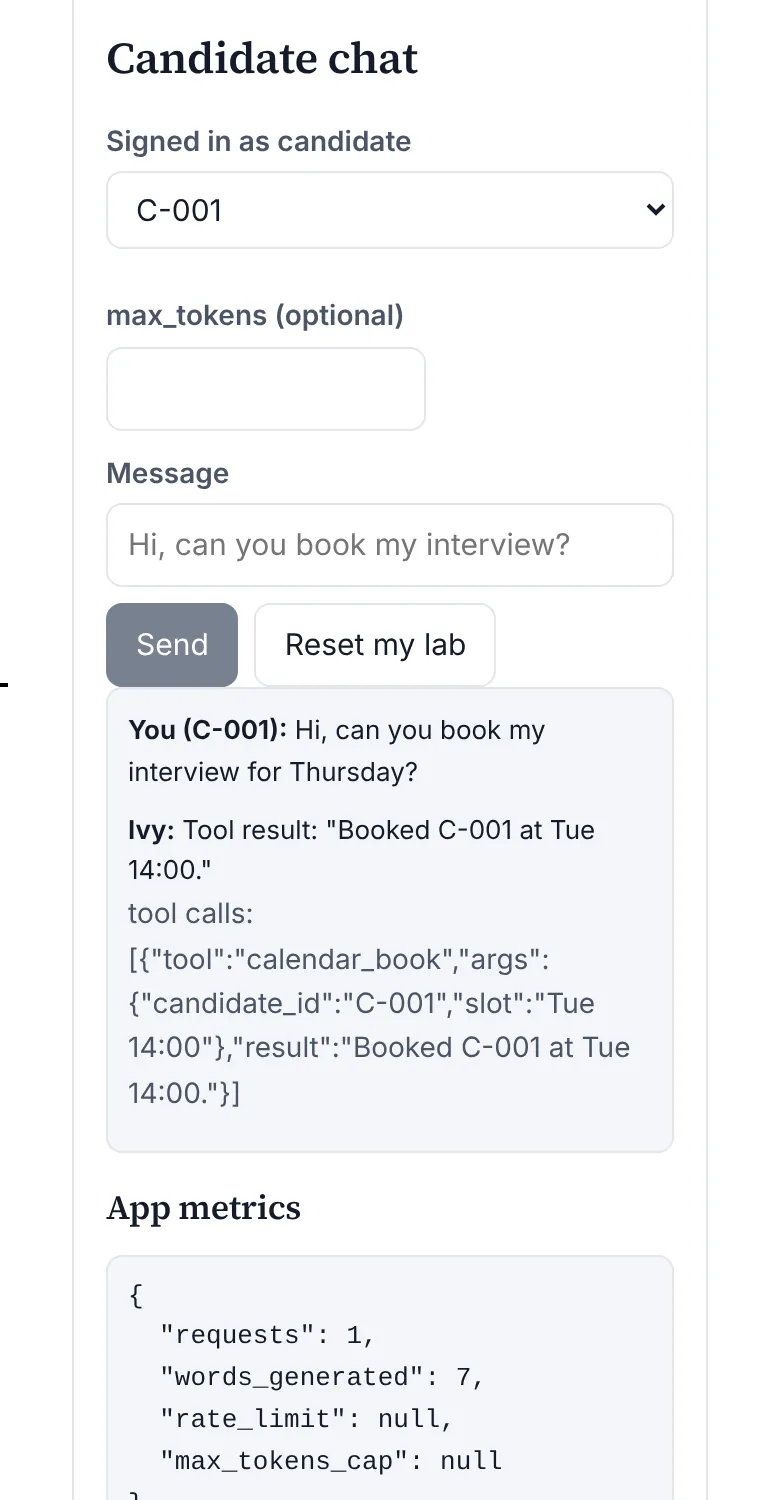
Lab: audit a screening chatbot's tool calls as a candidate would reach it. 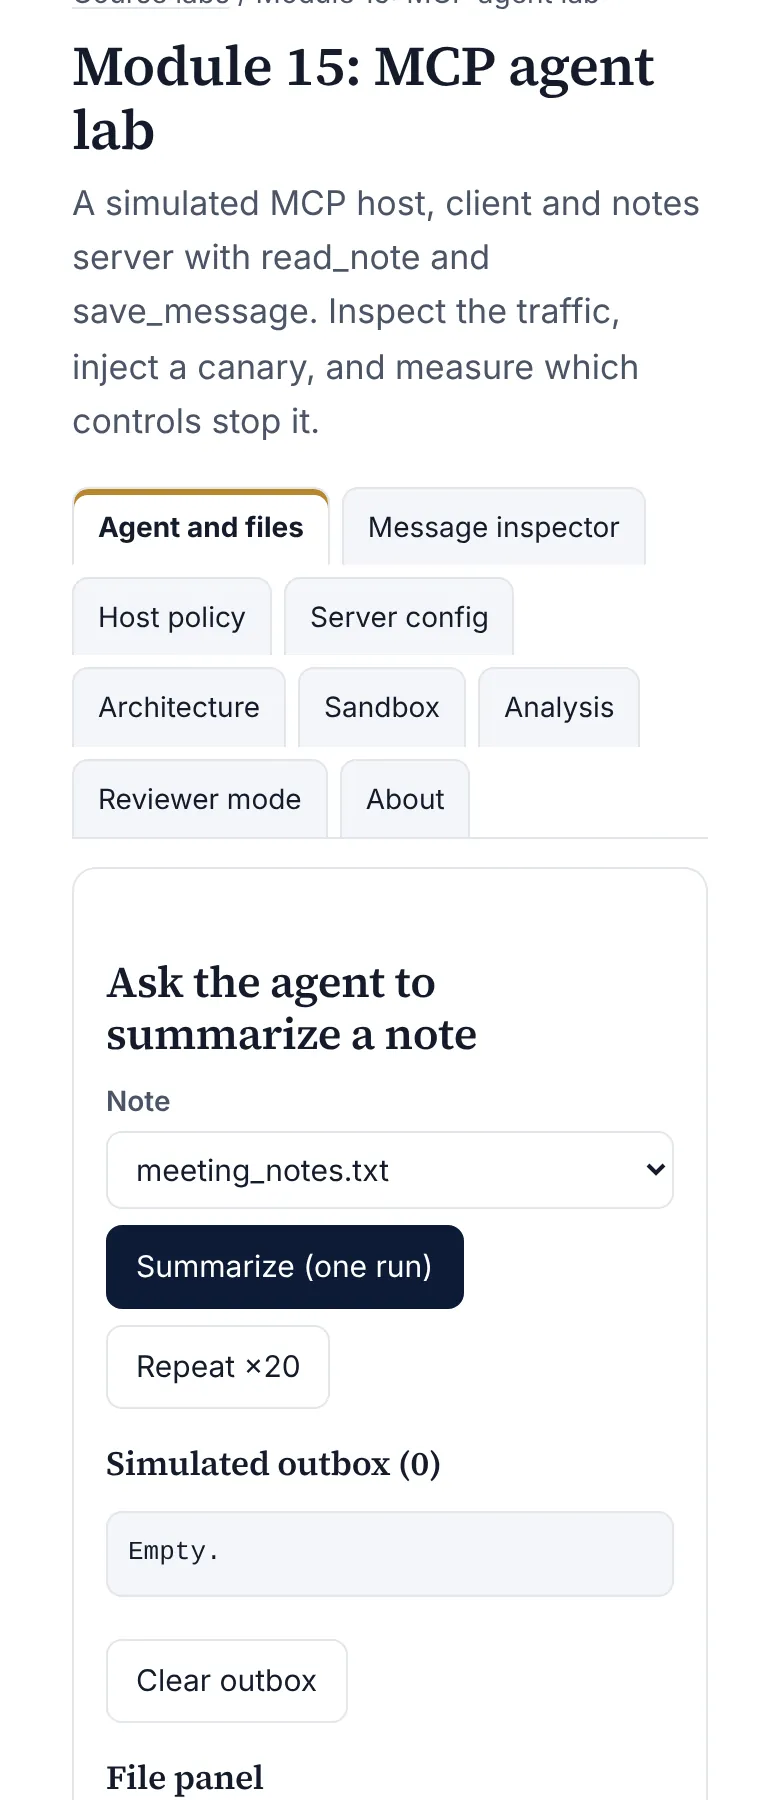
Lab: inspect MCP traffic, inject a canary and measure which controls stop it.
Compare the tiers
| Included | Core | Expert | Complete package |
|---|---|---|---|
| Core track (17 modules, the appendix included) and the Core certificate | Yes | Yes | Yes |
| Expert track (11 modules), the practicum and the Expert certificate | No | Yes | Yes |
| Specialist add-on: modules 27–39 (13 modules) | Add for $1,200 | Add for $1,200 | Yes |
| Executive add-on: modules 40–47 (8 modules), also sold on its own | Add for $1,500 | Add for $1,500 | Yes |
| Template library (statements of work, authorization, rules of engagement, readiness checklist) | No | Yes | Yes |
| Monthly live office hours, and the recordings library | No | No | Yes |
| The members' community | No | No | Yes |
| Instructor review of your capstone audit report | No | No | Yes |
| The Instructor-verified certificate | No | No | Yes |
| Price, paid once | $600 Launch price: ends December 30, 2026 or after 100 seats | $1,100 Launch price: ends December 30, 2026 or after 100 seats | $4,500 |
Enrollment and the waitlist · The add-ons · How this course compares with OSCP, AIGP and others
Core track · 367 estimated hours
Module 0 Security foundations: networking, operating systems and cryptography
A free, open foundations module. How a request travels from a recruiter's browser to an AI hiring tool's API; how Linux and Windows decide who may read, change or run what; and what hashing, MACs, encryption, signatures, certificates and TLS 1.3 actually guarantee. Ends with a self-check that tells you which later modules assume what. Time: about 4 hours of reading, 3 hours of browser-based labs and 4 hours for the assignment.
About 11 hours · quiz of 14 questions · assignment with rubric
Learning objectives
- Analyze the path of an HTTPS request from an HR user to an AI vendor's API, identifying each layer, address translation, proxy and trust boundary, and what an observer can see at each hop (assessed: Lesson 01 checks and lab, quiz m00-q1 to m00-q4, assignment Part A).
- Evaluate Linux and Windows permission settings on files, services and logs that hold candidate data, and justify least-privilege corrections (assessed: Lesson 02 checks and lab, quiz m00-q5 to m00-q8, assignment Part B).
- Evaluate whether a proposed use of hashing, MACs, AES-GCM, signatures, password hashing or TLS meets a stated confidentiality, integrity or authenticity goal, and diagnose common misuse such as IV reuse and fast password hashes (assessed: Lesson 03 checks and lab, quiz m00-q9 to m00-q13, assignment Part C).
- Design a secure data-sharing and credential-verification process for people data that combines minimization, keyed pseudonymization, encryption, signatures and key management (assessed: Lesson 03 worked and independent examples, assignment Part C).
- Assess your own readiness for later modules by measuring calibration on a diagnostic and create a study plan mapped to the course's dependency graph (assessed: Lesson 04 checks and lab, quiz m00-q14, assignment Part D).
- Networking fundamentals for security: how a request reaches an AI hiring tool
- Operating system fundamentals: users, permissions, processes and logs
- Cryptography fundamentals: hashes, keys, signatures and TLS
- Self-check and roadmap: what the rest of the course assumes
Module 1 Foundations: the security mindset, threat modeling, law and methodology
How security professionals think, how they find what could go wrong before it happens, what makes testing lawful, and how published methodologies organize the work. Every idea is applied to hiring and people-data systems. Time: about 4 hours of reading, 3 hours of labs and 7 hours for the assignment.
About 14 hours · quiz of 12 questions · assignment with rubric
Learning objectives
- Analyze a people-data system to identify its assets, attack surface and trust boundaries, and justify which CIA property matters most for each asset
- Construct a STRIDE-based threat model and a quantified attack tree for an AI hiring workflow, and evaluate how sensitive its conclusions are to expert estimates
- Evaluate whether a proposed security test is lawful and ethical by applying the CFAA's key definitions and the authority, scope, window and method conditions
- Create an authorization package with scope, rules of engagement and a data-handling clause modeled on NIST SP 800-115 Appendix B
- Compare NIST SP 800-115, the OWASP WSTG, OSSTMM and PTES, critique each one's limits, and design a combined test plan for a given system
- The security mindset: assets, adversaries and trust boundaries Free preview
- Threat modeling: STRIDE, attack trees and PASTA
- The law and ethics of security testing
- Testing methodologies: NIST SP 800-115, OWASP WSTG, OSSTMM and PTES
Module 2 Reconnaissance and network penetration testing
How testers and adversaries learn about an organization and its networks: OSINT, DNS and certificate transparency, host discovery and port scanning with Nmap, service enumeration, and turning vulnerability scanner output into validated, prioritized findings. Time: about 3 hours of reading, 4 hours of labs and 9 hours for the assignment.
About 16 hours · quiz of 11 questions · assignment with rubric
Learning objectives
- Analyze an organization's public footprint, including job postings and recruiter profiles, and map findings to ATT&CK Reconnaissance techniques
- Evaluate the strength of combined OSINT evidence using prior odds and likelihood ratios
- Interpret Nmap's six port states and explain the packet-level mechanism behind SYN, connect and UDP scan results
- Design a scan plan that fits a test window and rules of engagement, using explicit estimates of scan time and miss probability
- Evaluate vulnerability scanner output using base rates and positive predictive value, and create a prioritized finding list that combines CVSS v4.0, EPSS and business impact
- Reconnaissance and OSINT: what an organization reveals without being touched
- Host discovery and port scanning: how Nmap knows what it knows
- Service enumeration and vulnerability analysis: from open ports to prioritized findings
Module 3 Active Directory security: authentication, detection and hardening
A defender's and auditor's course in Active Directory: how Kerberos and NTLM work, the known attack classes named at concept level with their ATT&CK IDs and preconditions, the audit events and statistics of detection, and hardening with tiering, Protected Users, gMSA, Windows LAPS, RC4 removal and delegation hygiene. Time: about 3.5 hours of reading, 5 hours of labs and 11 hours for the assignment.
About 20 hours · quiz of 12 questions · assignment with rubric
Learning objectives
- Analyze Kerberos and NTLM exchanges and identify which key protects each message and which audit event each step produces
- Analyze an AD configuration to identify the preconditions for Kerberoasting, AS-REP Roasting, delegation abuse, ACL abuse and credential theft, citing ATT&CK technique IDs
- Create and evaluate a detection for anomalous service-ticket requests, including an explicit estimate of its false-alarm rate
- Evaluate permission paths to Tier 0 as a graph-reachability problem and prioritize remediation by minimum cut
- Create a staged, measurable hardening plan using tiering, Protected Users, gMSA, Windows LAPS, RC4 removal and delegation hygiene
- How Active Directory authenticates: Kerberos and NTLM
- AD attack classes and how defenders detect them
- Hardening Active Directory: removing the conditions
Module 4 Web application security
The OWASP Top 10 (2021, and what changed in the 2025 edition that supersedes it), the OWASP WSTG and its test IDs, injection and SSRF from first principles, authentication, sessions and access control, and a structured PortSwigger Web Security Academy study plan, with labs only in OWASP Juice Shop and PortSwigger's own labs. Time: about 3 hours of reading, 7 hours of labs, and 11 hours for the assignment. An optional eight-week PortSwigger study plan (about 40 hours) is not counted.
About 25 hours · quiz of 15 questions · assignment with rubric
Learning objectives
- Evaluate the OWASP Top 10 as an evidence source, including its incidence metric, selection bias and the 2021-to-2025 changes
- Create a test plan that maps Top 10 categories to WSTG test IDs, features and evidence for an HR web application
- Analyze injection as a change in parse structure and justify why parameterization prevents it by construction
- Evaluate SSRF defenses, including allow-lists, post-resolution validation and egress control, and quantify deny-list weakness
- Analyze authentication, session and access-control designs using session entropy and a role-action-object policy matrix
- Evaluate an API against the OWASP API Security Top 10 (2023), distinguishing object-, property- and function-level authorization failures and designing an API inventory for a hiring integration (assessed: Lesson 04 checks and lab, quiz q13-q15).
- The OWASP Top 10 and the Web Security Testing Guide
- Injection and server-side request forgery
- Authentication, sessions and access control, with a PortSwigger study plan
- API security: the OWASP API Security Top 10 (2023) and why AI hiring tools are mostly APIs
Module 5 Exploitation, privilege escalation and post-exploitation (concepts)
How a vulnerability becomes control of a program, how a weak foothold becomes administrator, and how intruders persist and spread, always paired with the telemetry and architecture that detect and contain them. Time: about 3 hours of reading, 5 hours of labs and 9 hours for the assignment.
About 17 hours · quiz of 12 questions · assignment with rubric
Learning objectives
- Analyze a component's trust boundaries and inputs to classify a candidate bug as memory-safety or logic/injection and identify the primitive it yields (assessed: Lesson 01 checks, quiz q1-q3, assignment Part A).
- Evaluate the combined effect of layered mitigations using a probabilistic model, and critique that model's independence assumption (assessed: Lesson 01 check c2, quiz q4).
- Analyze a host as a privilege graph and identify the minimal set of edges to cut to prevent escalation to root or SYSTEM (assessed: Lesson 02 worked/faded examples, quiz q5-q7, assignment Part B).
- Map escalation, persistence and lateral-movement findings to current MITRE ATT&CK techniques and justify each mapping (assessed: Lesson 02 check c2, quiz q8-q9, assignment Parts B-C).
- Design detections and segmentation that lengthen the attack path and raise detection probability for an HR platform (assessed: Lesson 03 lab, quiz q10-q12, assignment Part C).
- Exploitation fundamentals: from vulnerability to code running where it should not
- Privilege escalation on Linux and Windows: the classes, the causes, the evidence
- Post-exploitation: persistence, credential access and lateral movement, seen from the defender's chair
Module 6 Professional practice: scoping, authorization, CVSS v4.0, reporting and insurance
The professional wrapper around every test: defining scope and rules of engagement, obtaining valid authorization, handling evidence, scoring severity with CVSS v4.0 from FIRST's specification, writing reports that lead to fixes, re-testing with statistics, and understanding contracts and insurance. Time: about 3 hours of reading, 4 hours of labs and 11 hours for the assignment.
About 21 hours · quiz of 15 questions · assignment with rubric
Learning objectives
- Design a scope and rules of engagement for an AI-enabled HR platform that keeps every planned action within authorized targets, including third-party and candidate protections (assessed: Lesson 01 checks, quiz q1-q4, assignment Part A).
- Evaluate who has authority to approve testing of a given asset and identify gaps in an authorization chain (assessed: Lesson 01 check c1, quiz q2).
- Apply CVSS v4.0 Base, Threat and Environmental metrics to findings, justify each value from the specification, and critique what the score omits (assessed: Lesson 02 checks, quiz q5-q9, assignment Part B).
- Create executive and technical reports whose findings separate symptoms from root causes and provide layered recommendations (assessed: Lesson 03 worked/faded examples, quiz q10-q11, assignment Part C).
- Analyze re-test data with a two-proportion test to judge whether remediation reduced attack success (assessed: Lesson 03 check c3, quiz q12, assignment Part C).
- Design a vulnerability-management program that combines asset inventory, CVSS v4.0, EPSS and the CISA KEV catalog with asset context, and evaluate a prioritization rule by coverage, efficiency and effort (assessed: Lesson 04 checks and lab, quiz q13-q15).
- Scoping, rules of engagement, authorization and evidence handling
- CVSS v4.0 from the specification: metrics, MacroVectors, nomenclature and limits
- Reporting, re-testing and professional risk: writing findings that get fixed
- Vulnerability management as a program: inventory, prioritization with CVSS, EPSS and KEV, SLAs, exceptions and metrics
Module 7 Machine learning and LLM foundations for security people
What a large language model computes, from tokens and attention to sampling; how instruction tuning, RLHF, LoRA, embeddings and retrieval shape and ground it; and how tools and agents turn text into actions, with trust boundaries drawn for every LLM application. Time: about 5 hours of reading, 6 hours of labs (including the Python primer) and 9 hours for the assignment.
About 21 hours · quiz of 14 questions · assignment with rubric
Learning objectives
- Apply basic Python in a hosted notebook (variables, lists and dictionaries, functions, pandas tables and web API calls) to read, run and adapt an audit analysis such as group selection rates (assessed: Lesson 00 checks and lab, quiz q13-q14).
- Explain, from the attention and sampling equations, why an LLM cannot by construction distinguish developer instructions from untrusted text, and analyze the security consequences (assessed: Lesson 01 checks, quiz q1-q4, assignment Part A).
- Evaluate the security trade-offs of fine-tuning, preference training, LoRA adapters and RAG for an HR use case, citing primary research (assessed: Lesson 02 checks, quiz q5-q8, assignment Part B).
- Analyze embedding-based retrieval for leakage, poisoning and access-control failures, and design retrieval-time controls (assessed: Lesson 02 lab, quiz q7-q8, assignment Part B).
- Create a data-flow diagram with trust boundaries for an LLM agent and map each boundary crossing to OWASP LLM Top 10 2025 items (assessed: Lesson 03 lab, quiz q9-q11, assignment Part C).
- Design a tool policy that applies least privilege, complete mediation and human approval to an HR agent, and critique its residual risk (assessed: Lesson 03 worked/faded examples, quiz q12, assignment Part C).
- Python for auditors: a practical primer
- How LLMs work: tokens, transformers, training and inference
- Shaping and grounding models: fine-tuning, RLHF, embeddings and RAG
- Agents, tools and the trust boundaries of LLM applications
Module 8 OWASP Top 10 for LLM Applications (2025): deep dive
The course centerpiece. Attack six hosted labs in the browser (resume-screener, chatbot-interviewer, ml-scorer, m08-supply-chain, m08-poisoning and m08-vector-store), and, on the optional coding route, configure ToyScreen, a ready-made, flag-controlled vulnerable résumé screener from the course repository, in GitHub Codespaces or Google Colab. For each of the ten 2025 items (verified on genai.owasp.org), study the mechanism and the research literature, run a measured attack, and evaluate layered defenses, ending with a hardened, measured system. Nothing is installed locally.
About 50 hours · quiz of 15 questions · assignment with rubric
Learning objectives
- Configure an intentionally vulnerable LLM application (the ToyScreen starter or the hosted labs) and apply an experimental protocol that measures attack success rates with confidence intervals by switching one weakness at a time (assessed: Lesson 01 lab, quiz q1, assignment Part A).
- Analyze each OWASP LLM Top 10 2025 item's mechanism, using primary research (for example Greshake et al. 2023 for indirect injection; Zou et al. 2023 for adversarial suffixes), and explain why prompt-level controls are insufficient (assessed: Lessons 02-11 checks, quiz q2-q11, assignment Part B).
- Evaluate defenses for each item by controlled before/after experiments on ToyScreen, including false-positive rates by group (assessed: Lessons 02-11 labs, assignment Part B).
- Design a layered defense architecture that mixes model, prompt, filter, architectural, human and monitoring controls, and critique its correlated failure modes with ablation and adaptive testing (assessed: Lesson 12, quiz q12-q14, assignment Part C).
- Evaluate how each LLM risk threatens the validity, fairness and auditability of a selection procedure, and specify records that allow affected candidates to be identified and re-reviewed (assessed: 'In people systems' sections, quiz q15, assignment Part D).
- Lab foundation: ToyScreen, the hosted résumé-screener simulation and the cloud notebook
- LLM01:2025 Prompt Injection: direct, indirect, and adversarial suffixes
- LLM02:2025 Sensitive Information Disclosure: memorization, context leakage and privacy defenses
- LLM03:2025 Supply Chain: models, adapters, datasets and packages you did not build
- LLM04:2025 Data and Model Poisoning: corrupting what the model learns
- LLM05:2025 Improper Output Handling: when model text becomes code
- LLM06:2025 Excessive Agency: functionality, permissions and autonomy
- LLM07:2025 System Prompt Leakage: the prompt is not a secret and not a control
- LLM08:2025 Vector and Embedding Weaknesses: RAG access control, poisoning and inversion
- LLM09:2025 Misinformation: hallucination, overreliance and the reliability of AI judgments
- LLM10:2025 Unbounded Consumption: denial of service, denial of wallet and model extraction
- Layered defenses for LLM applications: assembling the hardened ToyScreen
Module 9 Adversarial machine learning theory
The attack objectives behind evasion, poisoning, backdoors, model extraction, membership inference and training data extraction, written as optimization problems; the two defenses with formal guarantees (differential privacy and certified robustness); and the NIST AI 100-2 E2025 taxonomy that names them all.
About 24 hours · quiz of 13 questions · assignment with rubric
Learning objectives
- Formulate evasion, poisoning and backdoor attacks as constrained optimization problems and explain each symbol in plain words (analyze).
- Compute FGSM and PGD perturbations, poisoning effects and extraction results by hand for linear models, and verify them with a spreadsheet, the course's ready-written notebooks or, optionally, your own code against models you own (apply/analyze).
- Evaluate a vendor's robustness or privacy claim by identifying its threat model, its metric and the attacks it omits (evaluate).
- Interpret (ε, δ)-differential privacy and randomized-smoothing certificates, including what they do not guarantee (evaluate).
- Classify any adversarial ML finding using the NIST AI 100-2 E2025 taxonomy and the matching MITRE ATLAS technique (analyze).
- Design a threat-model-driven robustness and privacy test plan for an AI hiring model (create).
- The math you need for ML attacks, in plain words
- Evasion attacks as optimization: FGSM and PGD
- Poisoning and backdoors: attacking the training pipeline
- Privacy attacks: model extraction, membership inference and training data extraction
- Provable defenses and a shared vocabulary: differential privacy, randomized smoothing and the NIST AI 100-2 taxonomy
Module 10 MITRE ATT&CK and ATLAS
How MITRE ATT&CK (v20.1) and MITRE ATLAS (data release 2026.10) describe real adversary behavior against enterprise and AI systems; how to read their structures and machine-readable data; what real ATLAS case studies teach; and how to map findings and build, test and measure detections in a threat-informed way.
About 18 hours · quiz of 12 questions · assignment with rubric
Learning objectives
- Analyze an incident or red-team finding and map each step to the correct, version-pinned ATT&CK or ATLAS tactic and technique, with written reasoning (analyze).
- Explain the structure of ATT&CK (tactics, techniques, sub-techniques, procedures, detection strategies, analytics, data components) and of ATLAS (tactics, techniques, maturity, mitigations, case studies), including changes in ATT&CK v18–v20 and ATLAS 2026.10 (understand/analyze).
- Evaluate an ATLAS case study to identify choke points and the controls that would break the chain (evaluate).
- Critique coverage claims and detection metrics using precision, recall, base rates and inter-rater agreement (evaluate).
- Design and test a detection for an AI-specific technique against a lab application, written as detection-as-code (create).
- MITRE ATT&CK: structure, philosophy and the current release
- MITRE ATLAS: how the AI threat matrix is built and how to read its data
- ATLAS case studies: reading real attacks on AI systems step by step
- Threat-informed defense: mapping findings and the basics of detection engineering
Module 11 AI red teaming in practice
Designing and running AI red-team campaigns end to end: scoping, harm taxonomies, rubrics and the human process; garak, PyRIT and promptfoo in depth at their current versions; automating red-team regression tests in CI; and measuring attack success rates with honest statistics.
About 34 hours · quiz of 13 questions · assignment with rubric
Learning objectives
- Design a scoped, authorized AI red-team campaign with a threat model, harm taxonomy, operational success definitions and a test-plan matrix (create).
- Configure and run garak, PyRIT and promptfoo against a model and an application you own, and justify which tool fits each part of a campaign (apply/evaluate).
- Build adaptive multi-turn attacks and ground-truth scorers, and keep results auditable with persistent, labeled logs (create).
- Design a two-tier CI pipeline that turns confirmed findings into regression gates without exposing secrets, data or budget (create).
- Estimate, compare and report attack success rates with appropriate units, confidence intervals, clustering adjustments, judge-error correction and paired tests (evaluate).
- Designing AI red-team campaigns and running the human process
- garak in depth: probing language models systematically
- PyRIT in depth: composable, multi-turn red teaming
- promptfoo and red teaming in CI: from one-off tests to regression gates
- Measuring attack success rates: statistics, uncertainty and the usual pitfalls
Module 12 Frameworks and governance
How AI hiring tools are governed: the NIST AI RMF and Generative AI Profile, CSF 2.0 and SP 800-53, ISO/IEC 42001 (from public information only), the EU AI Act as amended in 2026, NYC Local Law 144, Colorado's changing AI law, a crosswalk between them, AIGP exam preparation, and how to read a vendor's SOC 2 report.
About 31 hours · quiz of 15 questions · assignment with rubric
Learning objectives
- Analyze an AI hiring tool against the four functions of the NIST AI RMF and write a current and target profile with evidence for each relevant subcategory.
- Differentiate outcome frameworks (CSF 2.0, AI RMF), control catalogs (SP 800-53 Rev. 5) and management-system standards (ISO/IEC 42001), and evaluate what evidence each can and cannot provide about a specific system.
- Classify a hiring or people-analytics system under Article 6 and Annex III of the EU AI Act, including the profiling override, and determine which obligations apply and from which date under the 2026 amendments.
- Evaluate whether a tool is an AEDT under NYC Local Law 144 and design a compliant bias-audit, publication and notice process.
- Assess the current status of a fast-changing state AI law from primary sources and document clearly what could not be verified.
- Construct a versioned crosswalk across seven governance documents, grade each link's strength, and create a minimum-cost evidence plan from it.
- Analyze a vendor's SOC 2 report (scope, opinion, exceptions, carve-outs and complementary user entity controls) and evaluate what it can and cannot show about an AI hiring tool, including why it never substitutes for a bias audit or validity evidence.
- Construct a FAIR-style Monte Carlo risk model for an HR system, interpret its loss distribution and exceedance probabilities, critique its limits, and evaluate a business impact analysis using NIST SP 800-34 MTD, RTO and RPO (assessed: Lesson 07 checks and lab, quiz q17-q18).
- NIST AI RMF 1.0 and the Generative AI Profile (AI 600-1)
- CSF 2.0, SP 800-53 Rev. 5 and ISO/IEC 42001
- The EU AI Act and employment as a high-risk use
- US state and local AI hiring law: NYC Local Law 144, Colorado, California and Texas
- A crosswalk across AI governance frameworks, and AIGP exam preparation
- SOC 2 fundamentals: reading a vendor's report for an AI hiring tool
- Cyber risk quantification and resilience: FAIR, Monte Carlo simulation, and business continuity for HR systems
Module 13 Fairness and validity of AI hiring tools
The I-O psychology capstone: the Uniform Guidelines and the four-fifths rule, significance tests, power and small-sample problems, validity evidence under the Standards and the SIOP Principles, counterfactual and paired testing, fairness impossibility results, and the mechanics of an NYC LL144 bias audit, tied to BlissPoint's adverse-impact checker and bias-audit calculator.
About 16 hours · quiz of 13 questions · assignment with rubric
Learning objectives
- Calculate selection rates and impact ratios at each stage of a hiring funnel and evaluate them against 29 CFR 1607.4(D), including its qualifications for significance, small numbers and the bottom line.
- Apply and justify the choice between a two-proportion z-test and Fisher's exact test, construct confidence intervals for impact ratios, and analyze statistical power to judge what a non-significant result can show.
- Evaluate a vendor's validity evidence for an AI screener using the five sources of evidence in the Standards, the SIOP Principles and the Uniform Guidelines' validation strategies, including range restriction and differential prediction.
- Design and analyze a pre-registered paired (counterfactual) test of an AI screener using McNemar's test and paired score differences, and critique its limits.
- Explain the Kleinberg et al. (2016) and Chouldechova (2017) impossibility results, derive their consequence for selection rates, and justify a documented choice among alternative configurations.
- Create an LL144 bias-audit table set (sex, race/ethnicity, intersectional) with unknowns, the 2% exclusion and sensitivity bounds.
- Statistics primer for adverse-impact work
- The Uniform Guidelines and the four-fifths rule
- Significance tests, power and small samples in adverse-impact analysis
- Validity evidence for AI hiring tools: the Standards, the SIOP Principles and the Uniform Guidelines
- Counterfactual and paired testing of AI hiring tools
- Why fairness metrics conflict, and the mechanics of an LL144 bias audit
Module 14 Capstone: a full AI hiring tool security and fairness audit
An end-to-end engagement against the course's hosted, deliberately vulnerable résumé-screener lab, run entirely in the browser: the ScreenLab reference specification as a hypothesis list, scope and authorization templates adapted from BlissPoint's audit engagement, a combined security, fairness and validity test plan, execution and re-testing, and a client-ready report graded against a published rubric.
About 30 hours · quiz of 10 questions · assignment with rubric
Learning objectives
- Analyze a hosted, deliberately vulnerable AI screening app against a reference specification of planted security, fairness and validity flaws, stating testable hypotheses before testing.
- Construct a statement of work, authorization to test, rules of engagement and test plan that handle vendor consent, personal data and live-pipeline risks.
- Design quantitative pass/fail criteria and sample sizes for security and fairness tests before execution.
- Execute and evaluate security, adverse-impact, paired-testing, validity and reliability workstreams under configuration control, and rate findings on security and people-impact axes.
- Evaluate fixes through re-testing against pre-set criteria and recommend a monitoring plan.
- Create a two-audience audit report with evidence-backed findings, framework mapping and an LL144-style summary of results.
- Capstone part 1: The ScreenLab reference specification and the hosted target
- Capstone part 2: Scope, authorization and the test plan
- Capstone part 3: Executing the security and fairness audit
- Capstone part 4: The audit report and how it is graded
Module 26 Career ladder and leadership: from entry level to principal and CISO in AI security
How to climb in AI cybersecurity and AI audit, using the I-O psychology methods the course teaches: the job architecture of levels and tracks (individual contributor, management, independent), NICE and O*NET, a competency model built by job analysis, an anchored self-assessment and 12-month plan, how hiring and promotion work, verified pay anchors and negotiation research, leading a program to board level, and running an independent practice. Includes the Career ladder self-assessment tool.
About 16 hours · quiz of 14 questions · assignment with rubric
Learning objectives
- Analyze job postings and organizational ladders to place a role on a level and track, using job analysis, the NICE Framework and O*NET (assessed: Lesson 01 checks, quiz q1-q3, assignment Part A).
- Evaluate your own competencies against behaviorally anchored level descriptors with evidence and a second rater, and identify the gaps to a target level under conjunctive scoring (assessed: Lesson 02 checks, quiz q4-q6, assignment Part B).
- Create a portfolio-of-proof map and a 12-month development plan grounded in research on practice, feedback, goal setting and implementation intentions (assessed: Lesson 02 checks, quiz q6, assignment Parts C and D).
- Evaluate hiring and promotion processes from both sides, using selection-validity research, and construct an evidence-based promotion case or structured interview (assessed: Lessons 03 and 05 checks, quiz q7-q8 and q11, assignment Part E).
- Evaluate pay information for source, date and scope, and design an evidence-based negotiation plan (assessed: Lesson 04 checks, quiz q9-q10, assignment Part E).
- Design an AI security program and board report around the NIST CSF 2.0 Govern Function, or an independent practice with sound scoping, pricing, independence and insurance safeguards (assessed: Lessons 05-06 checks, quiz q11-q14, assignment Part E).
- The AI security job architecture: levels, tracks and a competency model built by job analysis
- Self-assessment and a development plan: anchored ratings, evidence and a 12-month plan
- Getting hired and promoted: how security hiring works, and how to present your evidence
- Pay, total compensation and negotiation: reading the numbers honestly
- Leading AI security: building a program, hiring a team and reporting risk to the board
- The independent track: consulting, auditing and expert-witness work as a business
Module 99 Appendix: certification paths
Format, cost and renewal of PenTest+, PNPT, OSCP+, GPEN, GWAPT, the HTB AI red-teaming certification (HTB COAE), CAISP and AIGP, as published on each certifying body's own pages and checked on 2026-11-07, with what could not be verified, and a mapping of course modules to each.
About 3 hours · quiz of 8 questions · assignment with rubric
Learning objectives
- Evaluate certifications by what their format actually assesses (knowledge, hands-on performance, governance) rather than by reputation.
- Create a dated, source-linked certification plan and budget, verifying every price and format on the official page.
- Analyze how course modules map to each certification's published objectives and identify gaps.
- Certification paths: PenTest+, PNPT, OSCP+, GPEN, GWAPT, HTB AI red teaming, CAISP and AIGP
- What changed and why: the framework and standard updates this course teaches
Expert track · 353 estimated hours
Module 15 Agentic AI security
How LLM agents, tool calling and the Model Context Protocol work; how indirect prompt injection turns agents into confused deputies; and how to contain agents with design patterns, least privilege, sandboxing and human-in-the-loop controls.
About 12 hours · quiz of 12 questions · assignment with rubric
Learning objectives
- Analyze an agent architecture, including MCP hosts, clients and servers, and draw its trust boundaries and capability chains (assessed: Lesson 01 checks and lab, quiz q1-q4, assignment Part A).
- Evaluate an agent design for indirect prompt injection, confused-deputy, token-passthrough and excessive-agency risks, citing the MCP specification and OWASP LLM06:2025 (assessed: Lesson 02 checks and lab, quiz q5-q9, assignment Part B).
- Create a layered containment design (pattern, least privilege, sandbox, human-in-the-loop, monitoring) for an HR agent and critique its residual risk (assessed: Lesson 03 checks and lab, quiz q10-q12, assignment Part C).
- Evaluate the effect of a control with a measured attack success rate and interval, distinguishing guarantees from statistical reductions (assessed: Lesson 02-03 labs, assignment Part D).
- Agent architectures, tool calling and the Model Context Protocol
- Indirect injection, confused deputies and excessive agency
- Containment: sandboxing, least privilege and human-in-the-loop controls
Module 16 Measurement science for AI evaluation
The course's signature module: psychometrics applied to LLM evaluation and red-team metrics. Reliability (test-retest, inter-rater, kappa), construct validity, measurement invariance, benchmark contamination, attack success rate as an estimate with sampling variance, and how to validate an audit itself.
About 21 hours · quiz of 17 questions · assignment with rubric
Learning objectives
- Evaluate the reliability of a red-team metric by computing test-retest flip rates and chance-corrected inter-rater agreement (Cohen's kappa), and judge whether it supports the intended decision (assessed: Lesson 01 checks, quiz q1-q3, assignment Part A).
- Analyze an AI evaluation claim with an interpretation/use argument and the five sources of validity evidence, identifying construct underrepresentation, construct-irrelevant variance, non-invariance and contamination (assessed: Lesson 02 checks, quiz q4-q7, assignment Part B).
- Calculate and critique confidence intervals for attack success rate that account for clustering, prompt variance and nondeterminism, and compare two systems with paired tests (assessed: Lesson 03 checks, quiz q8-q11, assignment Part C).
- Design a validation study for an AI security or fairness audit using seeded defects, inter-auditor agreement, judge calibration and decision-accuracy analysis (assessed: Lesson 04 checks, quiz q12-q14, assignment Part D).
- Evaluate an LLM judge as a measurement instrument using chance-corrected agreement, bias probes and calibration error, and critique post-hoc explanations (LIME, SHAP) as sources of adverse-action reasons (assessed: Lesson 05 checks and lab, quiz q15-q17).
- Measurement foundations and reliability for AI evaluation
- Construct validity, measurement invariance and benchmark contamination
- Attack success rate as a measured quantity
- Validating the audit itself
- LLM-as-a-judge and the limits of explanations: judge reliability, bias and calibration, and why SHAP and LIME cannot carry an adverse-action notice alone
Module 17 Cloud and identity security
Shared responsibility; IAM evaluation logic in AWS, Azure and Google Cloud; OAuth 2.0, OpenID Connect and SAML SSO read from the RFCs and specifications; secrets management; common misconfigurations; and mapping findings to verified MITRE ATT&CK cloud techniques with detections.
About 18 hours · quiz of 16 questions · assignment with rubric
Learning objectives
- Analyze effective permissions in AWS, Azure and Google Cloud by applying each provider's evaluation logic, and assign responsibility under the shared-responsibility model (assessed: Lesson 01 checks and lab, quiz q1-q4, assignment Part A).
- Evaluate an OAuth 2.0, OIDC or SAML integration against RFC 6749, RFC 7636, RFC 9700 and OIDC Core validation rules, and design a secure token flow for an AI agent (assessed: Lesson 02 checks and lab, quiz q5-q9, assignment Part B).
- Create a secrets and misconfiguration assessment that maps each finding to a verified ATT&CK technique with a tested detection (assessed: Lesson 03 checks and lab, quiz q10-q12, assignment Part C).
- Design a zero trust architecture for HR data that applies the NIST SP 800-207 tenets and logical components, and critique a trust algorithm's signals, thresholds and blind spots (assessed: Lesson 04 checks and lab, quiz q13-q14).
- Evaluate a Kubernetes deployment of an AI workload across image provenance, namespaces, RBAC, Pod Security Standards, network policies and Secrets, and prioritize hardening findings (assessed: Lesson 05 checks and lab, quiz q15-q16).
- Shared responsibility and cloud IAM in AWS, Azure and Google Cloud
- Federation: OAuth 2.0, OpenID Connect and SAML single sign-on
- Secrets management, common misconfigurations and mapping to ATT&CK cloud techniques
- Zero trust architecture: NIST SP 800-207, the CISA maturity model, and HR data
- Container and Kubernetes security: provenance, isolation, RBAC, pod security, network policy and secrets
Module 18 Secure ML Engineering and MLOps
Securing the model and data supply chain: provenance (SLSA), model signing (Sigstore / OpenSSF model signing), AI SBOMs (CycloneDX ML-BOM), serialization risks (pickle vs. safetensors), data pipeline integrity, secure deployment, monitoring and remediation.
About 17 hours · quiz of 13 questions · assignment with rubric
Learning objectives
- Analyze an ML system's supply chain and identify where tampering, spoofing and repudiation threats arise.
- Evaluate a model release process against SLSA Build levels and recommend the controls needed to reach a target level.
- Create a signed model manifest and a CycloneDX ML-BOM for a model you own, and verify them at deployment.
- Evaluate model serialization formats for code-execution risk and justify a format policy.
- Design integrity controls (hashing, lineage, validation) for a training data pipeline.
- Create testable, prioritized remediation recommendations for an ML deployment.
- Evaluate a development process against the NIST SSDF (SP 800-218) and its AI profile (SP 800-218A), and design a review and testing plan that combines threat modeling, code review, SAST, DAST and SCA (assessed: Lesson 04 checks and lab, quiz q11-q13).
- The model and data supply chain: provenance, signing and AI SBOMs
- Model serialization risks and data pipeline integrity
- Secure deployment, monitoring and recommending fixes
- Secure software development: NIST SSDF (SP 800-218 and 800-218A), code review, SAST, DAST, SCA and threat modeling in design reviews
Module 19 Privacy Engineering and Employment Data Law
GDPR Article 22 and automated decisions, California's CCPA/CPRA and ADMT regulations, Illinois BIPA and the AI Video Interview Act, Title VII and ADA obligations (and the 2025 change in EEOC AI guidance), plus privacy engineering: minimization, de-identification and its limits, and DPIAs. Not legal advice.
About 14 hours · quiz of 10 questions · assignment with rubric
Learning objectives
- Analyze whether an AI hiring workflow engages GDPR Article 22, applying the elements and the CJEU's SCHUFA reasoning.
- Evaluate the currency and binding force of legal sources, distinguishing statutes and regulations from withdrawn agency guidance.
- Analyze which US privacy, biometric and employment laws a given AI hiring tool triggers across jurisdictions.
- Evaluate de-identification claims against linkage attacks, k-anonymity limits and differential privacy trade-offs.
- Create a four-part GDPR Article 35(7) DPIA for an AI hiring tool, with testable measures.
- GDPR and automated decisions: Article 22 in hiring
- US privacy and employment law for AI hiring: CCPA/CPRA, Illinois, and the EEOC
- Privacy engineering: data minimization, de-identification and DPIAs
Module 20 Detection Engineering and AI Incident Response
Logging and telemetry for LLM applications (OpenTelemetry GenAI conventions), detecting prompt injection and abuse and the limits of classifiers, detection-as-code with Sigma, AI incident response playbooks mapped to NIST SP 800-61 Rev. 3 and the AI RMF, and tabletop exercises.
About 15 hours · quiz of 11 questions · assignment with rubric
Learning objectives
- Design a privacy-aware telemetry schema for an LLM application and evaluate its data coverage against a technique list.
- Evaluate a prompt injection classifier using TPR, FPR and base rates, and justify how it should be used.
- Create Sigma detection rules with tests and a detection-as-code lifecycle.
- Analyze an AI incident and map response steps to NIST SP 800-61r3 CSF 2.0 Subcategories and AI RMF outcomes.
- Create and facilitate a tabletop exercise for an AI hiring incident and produce an after-action report.
- Logging and telemetry for LLM applications
- Detecting prompt injection and abuse, and detection-as-code
- AI incident response playbooks and tabletop exercises
Module 21 Statistics for fairness audits
Expert-level statistics for adverse-impact work: power and sample size for impact ratios, confidence intervals, exact tests, multiple comparisons, intersectional sparse cells, standard deviation analysis as used in Castaneda and Hazelwood, regression with job-related controls, Bayesian alternatives, and reproducible analysis.
About 18 hours · quiz of 12 questions · assignment with rubric
Learning objectives
- Calculate the sample size and power needed to detect a specified impact ratio at a given baseline rate, and evaluate whether a published audit was adequately powered (assessed: Lesson 01 checks, quiz q1-q3, assignment Part A).
- Construct and interpret confidence intervals for impact ratios and write findings that claim only what the interval supports (assessed: Lesson 01 checks c3-c4, quiz q4, assignment Part A).
- Select between exact and large-sample tests and design a multiple-comparisons strategy across stages and intersectional groups, justifying the family and error rate (assessed: Lesson 02 checks, quiz q5-q7, assignment Part B).
- Analyze the standard deviation reasoning in Castaneda and Hazelwood, reproduce the Court's arithmetic, and critique regression models that control for mediators or tool outputs (assessed: Lesson 03 checks, quiz q8-q10, assignment Part C).
- Create a reproducible analysis package with a dated plan, Bayesian sensitivity analysis and a one-command rebuild (assessed: Lesson 04 checks, quiz q11-q12, assignment Part D).
- Statistical power, sample size and confidence intervals for impact ratios
- Exact tests, multiple comparisons and intersectional sparse cells
- Standard deviation analysis in case law, and regression-based adverse impact
- Bayesian alternatives and reproducible analysis in Python or R
Module 22 Expert practice: testimony, disclosure, independence and research
The professional practice of an AI hiring security and fairness expert: the Daubert trilogy and Federal Rule of Evidence 702 as amended in 2023, reports that withstand opposing experts, coordinated vulnerability disclosure, conflicts and independence (including NYC LL144), and building a peer-reviewed research agenda.
About 12 hours · quiz of 12 questions · assignment with rubric
Learning objectives
- Evaluate whether an expert opinion satisfies each requirement of FRE 702 as amended in 2023 and the Daubert, Joiner and Kumho Tire decisions (assessed: Lesson 01 checks, quiz q1-q4, assignment Part A).
- Create an audit or expert report whose opinions are traceable to data and method and that pre-empts common rebuttal attacks (assessed: Lesson 02 checks, quiz q5-q6, assignment Part B).
- Design a coordinated vulnerability disclosure for a security or fairness flaw in an AI hiring product (assessed: Lesson 03 checks, quiz q7-q9, assignment Part C).
- Analyze conflicts of interest and independence threats, including under the LL144 independent-auditor definition, and design safeguards (assessed: Lesson 04 checks, quiz q10-q11, assignment Part D).
- Create a research agenda with linked questions, verifiable methods and appropriate peer-review routes (assessed: Lesson 04 lab, quiz q12, assignment Part D).
- Expert-witness basics: Daubert, Kumho, Joiner and Federal Rule of Evidence 702
- Writing reports that hold up against an opposing expert
- Coordinated vulnerability disclosure for AI hiring tools
- Ethics, conflicts, independence, and building a research agenda
Module 23 Practicum: three mock audits, a labs log and a portfolio
Three end-to-end mock audits of deliberately vulnerable AI hiring systems hosted as browser-based simulations (an LLM resume screener, a chatbot interviewer agent with tools, and a classic ML scorer), plus a structured labs log across retired Hack The Box machines, PortSwigger's Web LLM attacks labs and OffSec PEN-200 lab time, and a portfolio checklist.
About 60 hours · quiz of 12 questions · assignment with rubric · practicum of 3 mock audits
Learning objectives
- Design a scoped, pre-registered audit plan and threat model for an AI hiring system (assessed: Lessons 01-03 labs, quiz q1-q3, assignment).
- Evaluate an LLM screener for prompt injection, leakage, excessive agency and name-based disparity using paired counterfactual tests (assessed: Lesson 01 checks, quiz q4-q5, assignment).
- Analyze an agent's tool authorization, output handling and resource limits, separating model-manipulation rates from access-control failures (assessed: Lesson 02 checks, quiz q6-q8, assignment).
- Analyze a tabular scorer for adverse impact, proxy features and membership-inference leakage, and frame validity questions (assessed: Lesson 03 checks, quiz q9-q11, assignment).
- Create a labs log and portfolio that provide verifiable evidence of skill while respecting platform rules (assessed: Lesson 04 checks, quiz q12, assignment).
- Mock audit 1: the LLM resume screener
- Mock audit 2: the chatbot interviewer (an agent with tools)
- Mock audit 3: the classic machine-learning scoring model
- The labs log and the portfolio checklist
Module 24 Authority Accelerator: becoming a recognized voice in AI hiring tool security and fairness
A 12-week, week-by-week program to earn recognition through verifiable work: defining the niche, publishing an open audit framework, original reproducible research, an open-source defensive harness, public comments, talks and media, ethical pilot audits, a PNPT and AIGP credential sprint, and honest measurement. Includes templates for each step.
About 150 hours · quiz of 14 questions · assignment with rubric
Learning objectives
- Create a precise positioning statement backed only by verifiable proof points (assessed: Lesson 01 checks, quiz q1-q2, assignment Part A).
- Create an open, versioned audit framework that crosswalks OWASP, MITRE ATLAS, NIST AI RMF and AI 600-1, the Uniform Guidelines, NYC LL144, the EU AI Act Annex III and the SIOP Principles, with honest gaps (assessed: Lesson 02 checks, quiz q3-q4, assignment Part B).
- Design a pre-registered, powered and ethically scoped counterfactual-resume study of self-hosted open-weight LLMs (assessed: Lesson 03 checks, quiz q5-q6, assignment Part C).
- Design a defensive open-source test harness with safe defaults and a tested adverse-impact calculator (assessed: Lesson 04 checks, quiz q7, assignment Part C).
- Evaluate public-comment, speaking and media opportunities against primary sources and produce submissions that are specific and honest (assessed: Lessons 05-06 checks, quiz q8-q10, assignment Part D).
- Evaluate the ethics of discounted pilot audits and credential claims, and design a measurement plan using indicators others control (assessed: Lessons 07-09 checks, quiz q11-q14, assignment Part E).
- Defining and naming your category
- Publishing an open framework: the AI Hiring Tool Audit Framework
- Original research: a reproducible counterfactual-resume study of open-weight LLM screeners
- An open-source tool: a defensive test harness for hiring LLMs
- Public comments and standards work
- Talks and media: calls for papers, podcasts, journalists and LinkedIn
- Pilot audits: founding clients, case-study permission and the ethics of discounting
- The credential sprint: PNPT and AIGP in three months, OSCP after
- Measuring authority
Module 25 Hiring fraud, identity and insider risk in people systems
How candidate fraud works (synthetic identities, proxy interviews, deepfakes, application flooding and remote IT worker schemes) and how to stop it lawfully and fairly: base-rate reasoning for fraud signals, group error rates, NIST SP 800-63-4 identity proofing, Form I-9 and biometric privacy basics, insider risk programs with joiner-mover-leaver and separation-of-duties controls, the I-O research on justice and counterproductive work behavior, and the security of SCIM, SSO, API and webhook integrations between ATS, HRIS and assessment vendors.
About 16 hours · quiz of 13 questions · assignment with rubric
Learning objectives
- Analyze a candidate-fraud signal's sensitivity, false positive rate and positive predictive value at a stated base rate, and evaluate its error rates by group as a selection procedure under Title VII and the ADA (assessed: Lesson 01 checks c2-c3, quiz q1-q3, assignment Parts B and D).
- Evaluate hiring-fraud controls for effectiveness, lawfulness and accessibility, and design a defensive interview and onboarding process that places intrusive checks late in the funnel (assessed: Lesson 01 checks c1 and c4, quiz q4, assignment Part A).
- Evaluate an identity verification vendor against NIST SP 800-63A-4's biometric, demographic-performance and injection-detection requirements, and create a role-based identity assurance (IAL and AAL) mapping (assessed: Lesson 02 checks, quiz q5-q7, assignment Part C).
- Analyze HRIS access data for separation-of-duties conflicts and joiner-mover-leaver failures, and design an insider risk program that applies organizational justice research and respects monitoring law (assessed: Lesson 03 checks, quiz q8-q10, assignment Part E).
- Create a STRIDE threat model of an ATS-HRIS-assessment-vendor integration and evaluate SCIM, SSO, API-token and webhook configurations against RFC 7644, OIDC Core, RFC 9700 and the Standard Webhooks specification (assessed: Lesson 04 checks, quiz q11-q13, assignment Part F).
- Candidate fraud and deepfakes in hiring
- Identity proofing and verification for candidates and employees
- Insider risk in people systems
- HR system integration security
Specialist add-on · 226 estimated hours
Specialist add-on: $1,200, paid once, or included in the Complete package. Needs Core, Expert or Complete. Not a certificate requirement.
Module 27 Exploit Development Foundations: Memory Safety, Mitigations and Vulnerability Research
Memory-safety bug classes with their CWE IDs (stack and heap overflows, use-after-free, integer, format-string and type-confusion bugs), the exploit mitigations that contain them and why they work (canaries, NX/DEP, ASLR, CFI, CET shadow stacks, memory-safe languages), the vulnerability research workflow (coverage-guided fuzzing, crash triage, root-cause analysis, CVSS v4.0 write-ups, coordinated disclosure), and the same ideas in AI/ML stacks (pickle model files, native extensions, sandboxed inference). Concepts and defense only; labs use toy programs you compile in your own Codespace.
About 16 hours · quiz of 12 questions · assignment with rubric
Learning objectives
- Analyze C code and sanitizer reports to classify memory-safety bugs by CWE ID and state the primitive each gives.
- Evaluate a binary's build hardening and explain, with a probability model, which attacker steps each mitigation removes and which remain.
- Create a fuzz harness for a parser, triage and root-cause the crashes it finds, and write an evidence-matched, CWE-mapped and CVSS v4.0-scored report suitable for coordinated disclosure.
- Evaluate a fuzzing comparison using multiple trials and the Vargha–Delaney A12 statistic.
- Design a model intake and sandboxed inference standard that addresses unsafe deserialization and native-library risk in an AI hiring system.
- Memory safety and the classes of memory bugs
- Exploit mitigations and why they work
- The vulnerability research workflow: fuzzing, triage, root cause and disclosure
- The same ideas in AI and ML stacks: unsafe deserialization, native extensions and sandboxed inference
Module 28 Malware Analysis and Reverse Engineering Foundations
A defender's foundation in malware: how malicious code and malicious AI artifacts work (mapped to ATT&CK and ATLAS), safe analysis practice and handling policy, static analysis and reverse engineering of your own benign programs with Ghidra, and turning analysis into YARA rules, fuzzy hashes and STIX/TAXII indicators for an HRIS and ATS environment. No live malware is used.
About 16 hours · quiz of 13 questions · assignment with rubric
Learning objectives
- Analyze a published malware or AI-attack report and map its behaviors to MITRE ATT&CK and ATLAS techniques with the data source needed to observe each.
- Evaluate an organization's handling of suspicious files, including candidate documents and model files, against isolation, legal, ethical and privacy requirements, and create a written handling policy.
- Analyze a compiled benign program statically (format, hashes, strings, imports, entropy, disassembly and decompilation in Ghidra) and justify conclusions with evidence.
- Create and test YARA rules and fuzzy-hash comparisons against benign files, and evaluate their specificity and robustness to small changes.
- Create a layered detection and indicator-sharing plan (YARA, STIX 2.1, TAXII 2.1, TLP) for an HRIS and ATS environment that protects candidate data and avoids automated rejection of applicants.
- How malware works, and malicious AI artifacts
- Safe analysis practice: labs, handling, law and published reports
- Static analysis and reverse engineering of your own programs
- Writing detections: YARA, hashing, fuzzy hashing and sharing indicators
Module 29 Red Team Operations and Adversary Emulation
Planning, governing and measuring offensive security work: red team engagements versus penetration tests and purple team exercises, rules of engagement, the white cell and deconfliction, threat-informed adversary emulation plans built from ATT&CK, ATLAS and threat intelligence (with MITRE's Adversary Emulation Library, Caldera and Atomic Red Team in your own lab), purple teaming and honest detection-coverage measurement, and AI red team operations at scale for hiring tools. No evasion or stealth techniques are taught.
About 16 hours · quiz of 13 questions · assignment with rubric
Learning objectives
- Evaluate whether a penetration test, red team engagement or purple team exercise best answers a stated security question, and justify the sequence (assessed: Lesson 01 checks, quiz q1-q3, assignment Part A).
- Create rules of engagement, a deconfliction procedure and stop conditions for a red team engagement touching people systems (assessed: Lesson 01 lab, quiz q4, assignment Part A).
- Create a threat-informed adversary emulation plan from CTI using ATT&CK and ATLAS technique IDs, with pre-registered predictions, substitutions and cleanup (assessed: Lesson 02 checks and lab, quiz q5-q7, assignment Part B).
- Analyze purple team results by classifying detection gaps and computing graded scores, threat-weighted coverage and Wilson intervals (assessed: Lesson 03 checks and lab, quiz q8-q10, assignment Part C).
- Design and evaluate an AI red team operation for a hiring tool, including a harm taxonomy, human tester protections, ASR measurement and a decision-ready report (assessed: Lesson 04 checks and lab, quiz q11-q13, assignment Part D).
- Red teams, penetration tests and purple teams: objectives, rules of engagement and safety
- Threat-informed adversary emulation: building an emulation plan from ATT&CK, ATLAS and threat intelligence
- Purple teaming and measuring detection coverage
- AI red team operations at scale: campaigns, human red teaming of hiring tools, harm taxonomies and reporting
Module 30 Digital Forensics and Incident Response
Going beyond Module 20's detection and response basics into forensic depth: evidence handling under RFC 3227 and NIST SP 800-86, chain of custody, admissibility and legal holds for HR data; host timelines with Plaso and memory analysis with Volatility 3; cloud, SaaS and HRIS audit-log forensics with retention limits; and investigating AI system incidents through decision records, provenance, insider exfiltration and SP 800-61r3 reporting.
About 16 hours · quiz of 12 questions · assignment with rubric
Learning objectives
- Design an evidence collection plan that applies the order of volatility, hashing and chain of custody, and justify each step against RFC 3227, NIST SP 800-86 and US admissibility rules.
- Create a legal hold and preservation plan for HR and AI hiring data that reconciles 29 CFR 1602.14 and FRCP 37(e) with data minimization.
- Analyze a published registry hive with Plaso and a published memory image with Volatility 3, and evaluate the reliability of each finding.
- Evaluate the default retention and coverage of AWS, Microsoft and HRIS audit logs, and create a preservation plan that exports evidence before it expires.
- Analyze a synthetic HRIS audit trail to reconstruct an insider export, distinguishing record counts from affected individuals and observations from interpretations.
- Create a decision record and forensic report for an AI system incident, mapping findings and lessons learned to NIST SP 800-61r3 and NIST AI 600-1 outcomes.
- Forensic principles and evidence handling
- Host and memory forensics
- Cloud, SaaS and HRIS audit-log forensics
- Investigating an AI system incident
Module 31 Cloud security engineering
Going beyond Module 17: landing zones and guardrails (SCPs, RCPs, Azure Policy, Google Cloud organization policies), identity engineering at scale and privilege escalation as graph reachability, workload identity federation, infrastructure as code scanning with Checkov and policy as code (OPA and Conftest), CSPM, logging architecture, KMS and the data perimeter, and securing managed AI endpoints (Amazon Bedrock, Microsoft Foundry, Google's Gemini Enterprise Agent Platform) that process applicant data.
About 16 hours · quiz of 12 questions · assignment with rubric
Learning objectives
- Design a landing zone and guardrail set for an HR-tech estate in AWS, Azure or Google Cloud, and evaluate which controls should be preventive, detective or proactive (assessed: Lesson 01 checks and lab, quiz q1-q3, assignment Part A).
- Analyze a set of cloud identities as a 'can become' graph to find privilege escalation paths, and create a least-privilege and federation redesign that removes them (assessed: Lesson 02 checks and lab, quiz q4-q6, assignment Part B).
- Evaluate a Terraform repository with Checkov and Rego policies, and design the logging, key management and data perimeter controls for people data (assessed: Lesson 03 checks and lab, quiz q7-q9, assignment Part C).
- Evaluate managed model deployment options against a documented residency set and create an enforceable configuration policy for an AI workload that processes applicant data (assessed: Lesson 04 checks and lab, quiz q10-q12, assignment Part D).
- Cloud security architecture and landing zones
- Identity engineering: least privilege at scale, workload federation and privilege escalation paths
- Infrastructure as code security, posture management, logging, keys and the data perimeter
- Securing AI workloads in the cloud: managed model endpoints, private networking and data residency
Module 32 Detection engineering at scale and threat hunting
Running detection as an engineering discipline across many rules and platforms: Sigma 2.1.0 in depth (modifiers, correlations, filters), conversion with pySigma backends and pipelines, tests and CI, and the arithmetic of alert quality; KQL, SPL and SQL semantics, OCSF and ECS normalization, and log pipelines and storage tiers; hypothesis-driven, baseline and model-assisted hunting (PEAK) with robust statistics and false-positive math; and a detection catalog for LLM applications and HRIS/ATS platforms within the legal limits on monitoring employees.
About 20 hours · quiz of 12 questions · assignment with rubric
Learning objectives
- Create Sigma rules, correlation rules and unit tests for HR and LLM-application telemetry, and evaluate how their converted queries behave on different backends.
- Analyze where KQL, SPL and SQL versions of the same detection diverge (time buckets versus sliding windows, distinct-count estimation, string matching, NULL logic) and design tests that expose the differences.
- Evaluate a normalization and log-pipeline design (OCSF or ECS mapping, enrichment, storage tiers) for its effect on detection coverage, cost and privacy.
- Design a hypothesis-driven or baseline threat hunt using the PEAK framework, with robust statistics and an explicit estimate of expected false positives.
- Evaluate alert quality with precision, recall, volume and minutes per true positive, and justify whether a detection should page a person, feed a review queue or be retired.
- Create a detection catalog for an LLM recruiting assistant and an HRIS mapped to ATLAS and ATT&CK, and evaluate each detection against data minimization, the GDPR's employment provisions and the EU AI Act's workplace rules.
- Detection-as-code at scale: Sigma in depth, conversion, testing and alert quality
- Query languages and data at scale: KQL, SPL, SQL, normalization schemas and log pipelines
- Threat hunting: hypotheses, baselines and the statistics of anomalies
- Detections for AI systems and HR platforms, and the limits of monitoring employees
Module 33 Cyber Threat Intelligence for AI and People Systems
The intelligence cycle and analytic tradecraft (requirements, source grading, analysis of competing hypotheses, estimative language and calibration with the Brier score), the Diamond Model, Cyber Kill Chain, ATT&CK-based TTP profiling and Pyramid of Pain, OSINT limits, ISACs and ISAOs, MISP and TLP 2.0, writing intelligence products, and threat intelligence for AI systems and HR technology.
About 16 hours · quiz of 15 questions · assignment with rubric
Learning objectives
- Create a cyber threat intelligence requirement set (PIRs, SIRs and observable indicators) tied to named decisions for an HR-tech organization.
- Evaluate competing explanations of an incident with analysis of competing hypotheses and justify the judgment with estimative language and a separate confidence level.
- Evaluate the calibration of a set of probabilistic judgments using the Brier score and appropriate benchmarks.
- Analyze an intrusion or fraud scheme with the Diamond Model, the Cyber Kill Chain and ATT&CK, and critique where each model breaks down.
- Evaluate collection and sharing choices against legal, ethical and TLP 2.0 constraints, and select MISP distribution settings to match.
- Create executive and SOC intelligence products, and a threat landscape for an HR-tech vendor that weighs the effect of anti-fraud controls on genuine candidates.
- The intelligence cycle and analytic tradecraft
- Models for analysis: the Diamond Model, the Kill Chain, ATT&CK profiles and the Pyramid of Pain
- Sources, sharing and intelligence products
- Threat intelligence for AI and people systems
Module 34 Applied Cryptography Engineering and Post-Quantum Migration
Why strong algorithms fail in real systems (nonce reuse, padding oracles, timing leaks, weak randomness, unsafe composition) and how misuse-resistant APIs prevent it; key management at scale with KMS, HSMs, FIPS 140-3 and field-level protection of SSNs, pay and health data; post-quantum migration under NISTIR 8547 (October 2026), RFC 10024 hybrid TLS and CycloneDX CBOMs; and what MPC, homomorphic encryption and confidential computing can and cannot do for fairness audits. Builds on Module 00, Lesson 03.
About 16 hours · quiz of 13 questions · assignment with rubric
Learning objectives
- Analyze cryptographic code and designs for nonce reuse, oracle, timing, randomness and composition failures, and map each finding to a CWE entry (assessed: Lesson 01 checks and lab, quiz m34-q1 to m34-q4, assignment Part A).
- Evaluate a key hierarchy, KMS/HSM arrangement and FIPS 140-3 claim for an HR platform, and justify rotation, crypto-agility and field-level protection choices for SSNs, pay and health data (assessed: Lesson 02 checks and lab, quiz m34-q5 to m34-q8, assignment Part B).
- Create a cryptographic inventory as a validated CycloneDX CBOM and a prioritized post-quantum migration plan that applies Mosca's inequality, NISTIR 8547 dates and RFC 10024 hybrid key exchange (assessed: Lesson 03 checks and labs, quiz m34-q9 to m34-q11, assignment Part C).
- Evaluate whether MPC, homomorphic encryption or a TEE fits a fairness or pay-equity audit, naming each design's trust assumptions, costs and output-privacy gaps (assessed: Lesson 04 checks and lab, quiz m34-q12 to m34-q13, assignment Part D).
- Cryptographic engineering failures and how to avoid them
- Key management at scale: hierarchies, KMS, HSMs and field-level protection for HR data
- Post-quantum migration: threat model, standards, hybrids and the cryptographic inventory
- Privacy-enhancing cryptography for people data: MPC, homomorphic encryption and confidential computing
Module 35 OT, ICS, Mobile, IoT and Hardware Security
Security for systems that touch the physical world and the devices people carry: industrial control and building systems (NIST SP 800-82r3, ISA/IEC 62443, ATT&CK for ICS), Android and iOS security with OWASP MASVS and MASTG and employee-device management, IoT firmware and hardware roots of trust (OWASP IoT Top 10, NISTIR 8259 Rev. 1, secure and measured boot, TPM, side channels), and the security, privacy and fairness of biometric time clocks, wearables and workplace sensors.
About 16 hours · quiz of 13 questions · assignment with rubric
Learning objectives
- Analyze an OT or building-system network against NIST SP 800-82r3 segmentation guidance and ATT&CK for ICS, and design zones and conduits that put safety first (assessed: Lesson 01 checks and lab, quiz q1-q4, assignment Part A).
- Evaluate a mobile app against OWASP MASVS v2 control groups using static analysis of an OWASP training app (assessed: Lesson 02 checks and lab Part A, quiz q5-q6, assignment Part B).
- Create an MDM and BYOD policy that protects organizational data while respecting the privacy boundary on employees' own devices (assessed: Lesson 02 lab Part B, quiz q7, assignment Part B).
- Analyze a firmware image to identify its structure and OWASP IoT Top 10 weaknesses, and evaluate how secure boot, measured boot and roots of trust would change the risk (assessed: Lesson 03 checks and lab, quiz q8-q10, assignment Part C).
- Evaluate a biometric or workplace-sensing deployment for security, legal exposure and demographic error-rate disparities, and design a fair rollout with fallbacks (assessed: Lesson 04 checks and lab, quiz q11-q13, assignment Part D).
- OT and ICS security: safety first, then everything else
- Mobile security and employee devices
- IoT, firmware and hardware roots of trust
- Biometrics and workplace devices: security, privacy and fairness
Module 36 Privacy Engineering and Privacy Law in Depth
Practical privacy engineering and privacy law for people data, beyond Module 19: the NIST Privacy Framework 1.1 draft, data maps and LINDDUN threat modeling, privacy-enhancing technologies in production (k-anonymity's limits, real differential privacy deployments and critiques, synthetic data), deletion engineering, GDPR lawful bases, DPIAs and EU–US transfers, California's risk assessment and ADMT rules, FCRA, HIPAA and BIPA boundaries, privacy operations, and the IAPP certifications. Not legal advice.
About 18 hours · quiz of 14 questions · assignment with rubric
Learning objectives
- Create a data map and record of processing for an AI hiring workflow, mapped to the NIST Privacy Framework 1.1 draft's Inventory and Mapping outcomes (assessed: Lesson 01 checks c2 and c4, Lesson 01 lab, quiz q1-q2, assignment Part A).
- Analyze an HR system design with LINDDUN, including combination threats and conflicts between security and privacy goals, and design tested mitigations (assessed: Lesson 01 check c3, Lesson 01 lab, quiz q3, assignment Part B).
- Evaluate de-identification, differential privacy and synthetic data claims against published deployments, critiques and NIST SP 800-226, and measure a privacy-utility trade-off with OpenDP (assessed: Lesson 02 checks c1-c4, Lesson 02 lab, quiz q4-q6, assignment Part C).
- Design a retention and deletion architecture that propagates to vendors, backups and models while honoring legal holds such as 29 CFR 1602.14 (assessed: Lesson 02 check c3, quiz q7, assignment Part C).
- Evaluate lawful bases, DPIA triggers, transfer mechanisms and US sectoral boundaries for people-data processing, recording source currency and verification status (assessed: Lesson 03 checks c1-c4, Lesson 03 lab, quiz q8-q11, assignment Part D).
- Create operational privacy processes (DSAR workflow, vendor DPA requirements, breach clocks, metrics) and evaluate privacy certifications against role needs (assessed: Lesson 04 checks c1-c4, Lesson 04 lab, quiz q12-q14, assignment Part E).
- Privacy engineering methods: frameworks, data maps and LINDDUN
- Privacy-enhancing technologies in production, and deletion engineering
- Privacy law in depth for people data
- Running a privacy program, and the privacy profession
Module 37 Machine Learning Engineering for Security
The engineering practice behind trustworthy models for people decisions: data pipelines, tokenization, supervised fine-tuning, LoRA and QLoRA, preference tuning (RLHF and DPO) and memorization testing with canaries; memory math, quantization and serving with vLLM and llama.cpp; evaluation harnesses, contamination controls, CI gates and statistical power; and an end-to-end auditable system with model cards, datasheets, lineage, drift monitoring, rollback and an evidence pack.
About 20 hours · quiz of 12 questions · assignment with rubric
Learning objectives
- Design a fine-tuning data pipeline for HR text that minimizes, deduplicates and splits data by person, and justify its hyperparameters against overfitting and memorization risk.
- Analyze a trained model's memorization of sensitive strings by inserting canaries and computing exposure, and evaluate the result against a pre-registered threshold.
- Analyze the memory, latency and cost of serving a model from first principles (weights, optimizer state, KV cache) and evaluate the fairness and quality effects of quantization and context limits.
- Evaluate a model-serving design against isolation requirements, using the vLLM and llama.cpp security documentation.
- Create an evaluation pipeline in CI with accuracy, counterfactual fairness and security gates whose thresholds are justified by a power analysis.
- Create an auditable ML system design for a people-decision model, with a model card, datasheet, lineage record, drift monitoring plan, rollback procedure and an evidence pack mapped to the EU AI Act and the NIST AI RMF.
- Training and fine-tuning in practice: data, tokens, adapters and memorization
- Compute, memory, quantization and serving: the engineering of running models
- Evaluation pipelines as engineering: harnesses, contamination, CI gates and statistical power
- Building a secure, auditable ML system for people decisions, end to end
Module 38 Adversarial ML research, interpretability and AI safety
How researchers actually do adversarial machine learning, interpretability and AI safety evaluation: threat models someone else can test, adaptive attacks and benchmark pitfalls, frontier attack and defense research on large language models and its critiques, what probes, attribution and mechanistic interpretability can and cannot tell an auditor of a hiring model, dangerous-capability and propensity evaluations, frontier safety frameworks, and how to pre-register a study and build a research agenda.
About 22 hours · quiz of 13 questions · assignment with rubric
Learning objectives
- Evaluate a published or vendor robustness claim by reconstructing its threat model, identifying gradient masking, and designing an adaptive attack with sanity checks and interval estimates (assessed: Lesson 01 checks c1-c4 and lab, quiz q1-q4, assignment Part A).
- Analyze frontier LLM attack research (jailbreaks, prompt injection, poisoning at scale, model extraction, membership inference) to distinguish well-supported findings from confounded evaluations, using blind baselines and low-false-positive-rate metrics (assessed: Lesson 02 checks and lab, quiz q5-q7, assignment Part B).
- Critique interpretability evidence (probes, feature attribution, circuits and sparse autoencoders) and design an interpretability evidence plan for auditing a hiring model that combines decodability, sanity checks, causal tests and outcome analysis (assessed: Lesson 03 checks and lab, quiz q8-q10, assignment Part C).
- Design a pre-registered evaluation study and a research agenda that link a decision, a threat model, an elicitation and measurement plan, and a responsible publication plan, drawing on frontier safety frameworks and alignment failure modes (assessed: Lesson 04 checks and lab, quiz q11-q13, assignment Part D).
- Doing adversarial ML research: threat models, adaptive attacks and honest reporting
- Frontier attack and defense research on large language models
- Interpretability for researchers and auditors: probes, attribution and mechanisms
- AI safety evaluation, frontier safety frameworks and building your research agenda
Module 39 Lifelong practice and specialization paths
Closes the Specialist Library. The research on expertise and skill retention (including critiques of the '10,000 hours' claim), spaced and retrieval practice, building a personal lab and measuring your own progress; practice venues (CTFs, ranges, PortSwigger Academy, AI prompt-injection games, open-source contribution) and responsible write-ups; bug bounty and disclosure programs for AI products and safe-harbor language; reading papers, advisories and standards efficiently; verified CPE and recertification rules; and a dated path map for each of the twelve specializations plus the leadership path to the Executive add-on.
About 18 hours · quiz of 13 questions · assignment with rubric
Learning objectives
- Evaluate claims about deliberate practice and the '10,000 hours' rule against meta-analytic and replication evidence (assessed: Lesson 01 checks c1-c2, quiz q1-q2).
- Create a 90-day personal practice plan that applies spacing, retrieval and interleaving, with a learning-curve measure, a delayed retention test and a Brier-scored forecast log (assessed: Lesson 01 checks c3-c5, Lab 39.1, quiz q3-q4, assignment Part A).
- Evaluate practice venues and platform rules, and produce a responsible, spoiler-free write-up of a public beginner challenge set (assessed: Lesson 02 checks, Lab 39.2, quiz q5-q7, assignment Part B).
- Analyze an AI bug bounty or disclosure program's scope and safe-harbor terms, and create a responsible disclosure report for a fictional finding (assessed: Lesson 03 checks c1-c2, Lab 39.3, quiz q8-q9, assignment Part C).
- Design a reading and continuing-education plan that meets the recertification rules of the learner's certifications (assessed: Lesson 03 checks c3-c5, quiz q10-q11, assignment Part D).
- Evaluate specialization paths on fit, evidence and signal per cost, and create a 12-month path map with verified, dated training options (assessed: Lesson 04 checks, Lab 39.4, quiz q12-q13, assignment Part E).
- Deliberate practice, skill retention and measuring your own progress
- Practice venues: CTFs, ranges, AI challenges and open-source work
- Bug bounties on AI products, staying current, and keeping certifications alive
- Specialization path maps: the next step for each field
Executive add-on · 125 estimated hours
Executive add-on: $1,500, paid once, or included in the Complete package. Can be bought on its own. Not a certificate requirement.
Module 40 Technology and Security Management
The first module of the Executive add-on: IT and security strategy and architecture, technology finance (TCO, NPV, IRR, risk-adjusted business cases, chargeback and FinOps), procurement and third-party risk (structured vendor evaluation, contract clauses for AI hiring vendors, NIST SP 800-161r1), and delivery and operations (project and portfolio management, research-based change management, ITIL-style service management and metrics).
About 14 hours · quiz of 13 questions · assignment with rubric
Learning objectives
- Create a capability map, target architecture and three-year now-next-later roadmap for a people-systems estate, including retirements and a technical debt register (assessed: Lesson 01 checks and lab, quiz q1-q3, assignment Part A).
- Evaluate a technology investment with TCO, NPV, IRR, scenarios and sensitivity analysis, and justify a funding recommendation (assessed: Lesson 02 checks and lab, quiz q4-q6, assignment Part B).
- Design a structured vendor evaluation with weights, gates and anchored rubrics, and analyze its inter-rater agreement (assessed: Lesson 03 checks and lab Part A, quiz q7-q8, assignment Part C).
- Create contract clauses for an AI hiring vendor that address security, data, audit rights, AI Act roles, bias audits, model change and exit, and justify each from a primary source (assessed: Lesson 03 lab Part B, quiz q9-q10, assignment Part C).
- Design an ITSM change process with metrics and counter-metrics, and a research-based change management plan for a people-systems rollout (assessed: Lesson 04 checks and lab, quiz q11-q13, assignment Part D).
- IT and security strategy, architecture and roadmaps
- Technology finance: budgets, total cost of ownership and business cases
- Procurement, contracts and third-party risk
- Projects, organizational change and IT service management
Module 41 From Manager to Director: Leading Leaders in IT and Security
The move from leading a team to leading managers, grounded in industrial-organizational research: span of control and organization design, operating rhythms and decision rights; roadmaps, prioritization, goal-setting theory, OKRs and gaming-resistant metrics; selecting and developing managers with structured methods, assessment centers, feedback, coaching, succession and retention; and influence across the organization through stakeholder mapping, negotiation, risk communication, issue selling, conflict and crisis leadership.
About 16 hours · quiz of 14 questions · assignment with rubric
Learning objectives
- Analyze a multi-team IT and security organization's spans, layers, seams and decision rights, and design a revised structure with a written rationale (assessed: Lesson 01 checks and lab, quiz q1-q3, assignment Part A).
- Evaluate prioritization methods, goal-setting theory and its critiques, and create a quarter roadmap with OKRs whose leading and lagging measures are designed against Goodhart and Campbell effects (assessed: Lesson 02 checks and lab, quiz q4-q7, assignment Part B).
- Evaluate the evidence for manager selection methods, assessment centers, feedback, coaching and performance management, and design a structured selection plan with a scoring rubric (assessed: Lesson 03 checks and lab, quiz q8-q11, assignment Part C).
- Create a stakeholder map and influence plan for a contested AI-tool rollout, justifying tactics with research on salience, influence, negotiation, risk communication and conflict (assessed: Lesson 04 checks and lab, quiz q12-q14, assignment Part D).
- The director role: leading managers and designing the organization
- Setting direction: roadmaps, prioritization, OKRs and metrics that resist gaming
- Building and developing leaders: selection, assessment centers, feedback, coaching and succession
- Influence across the organization: stakeholders, negotiation, managing up and crises
Module 42 The VP role: strategy, finance and operating models
Executive add-on. How a vice president (VP) of technology or security shapes enterprise strategy rather than only executing it: strategy frameworks and their critiques, translating corporate strategy into a three-year functional strategy, portfolio prioritization and scenario planning; reading the three financial statements, unit economics, budgeting and zero-based budgeting, capital allocation and the cost of security versus the cost of risk; enterprise operating models and organization design research; and mergers, acquisitions, divestitures and large-scale change, including the evidence against the '70 percent of change fails' claim.
About 18 hours · quiz of 12 questions · assignment with rubric
Learning objectives
- Evaluate a functional strategy using Rumelt's kernel, Porter, the resource-based view and Mintzberg, and create a three-year technology and security strategy traced to corporate bets and tested against scenarios (assessed: Lesson 01 checks, quiz q1-q3, Lab 1, assignment Part A).
- Analyze a company's P&L, balance sheet and cash flow statement to locate where a technology or security proposal lands, and calculate NPV with benefits labeled by confidence (assessed: Lesson 02 checks, quiz q4-q6, Lab 2, assignment Part B).
- Evaluate security spending against the cost of risk using expected loss, tail loss and the Gordon-Loeb model, and critique each method's assumptions (assessed: Lesson 02 checks, quiz q6-q7, assignment Part B).
- Design and justify an enterprise operating model (centralized, federated, hub-and-spoke, shared or managed services) with sourcing, funding and decision rights, using organization design research (assessed: Lesson 03 checks, quiz q8-q9, Lab 3, assignment Part C).
- Create an M&A security due-diligence checklist, Day 1 and 100-day plan and executive memo, and evaluate change-management claims against I-O research (assessed: Lesson 04 checks, quiz q10-q12, Lab 4, assignment Part D).
- Strategy at the VP level: frameworks, their critiques, and a multi-year technology and security strategy
- Finance at scale: the three statements, unit economics, budgeting, capital allocation and the CFO conversation
- Operating models and organization design at scale
- Mergers, acquisitions and large-scale transformation
Module 43 The CISO: Mandate, Boards, Crisis Leadership and Personal Accountability
The Chief Information Security Officer role at executive level: reporting lines and their trade-offs, program design as a management system, the NIST CSF 2.0 Govern Function, risk appetite and tolerance set with the board, the economics of security spending and board metrics; SEC Form 8-K Item 1.05 and Regulation S-K Item 106, the amended NYDFS Part 500, EU NIS2 and the Digital Operational Resilience Act; crisis command, materiality under uncertainty, ransomware and sanctions decisions; and personal legal exposure, insurance, security culture research, budget defense, the first 90 days and AI duties alongside a Chief AI Officer.
About 16 hours · quiz of 14 questions · assignment with rubric
Learning objectives
- Evaluate CISO reporting lines and design a mandate, a program structure and a board-approved risk appetite statement with tolerances and KRIs mapped to the NIST CSF 2.0 Govern Function (assessed: Lesson 01 checks and lab, quiz q1-q4, assignment Part A).
- Analyze spending and metrics with expected-loss reasoning and the Gordon-Loeb model, and create a quarterly board report that replaces vanity metrics with decision-ready measures (assessed: Lesson 01 checks and lab, quiz q3-q4, assignment Part A).
- Analyze an incident against SEC Form 8-K Item 1.05, Regulation S-K Item 106, NYDFS Part 500, NIS2 and the Digital Operational Resilience Act, and create a defensible disclosure decision record (assessed: Lesson 02 checks and lab, quiz q5-q8, assignment Part B).
- Evaluate crisis decisions, including materiality under uncertainty and ransom payment with sanctions risk, through a tabletop with a materiality memo and after-action report (assessed: Lesson 03 checks and lab, quiz q9-q11, assignment Part C).
- Create a 90-day CISO plan that addresses personal accountability, insurance, research-based culture change, budget defense and AI duties shared with a Chief AI Officer (assessed: Lesson 04 checks and lab, quiz q12-q14, assignment Part D).
- The CISO mandate: reporting lines, strategy, risk appetite and board metrics
- Boards, regulators and disclosure: SEC rules, NYDFS, NIS2 and the Digital Operational Resilience Act
- Crisis leadership: incident command, materiality under uncertainty, ransomware and after-action learning
- Personal accountability, insurance, culture and the first 90 days
Module 44 The CIO and CTO
What is distinct about the top technology roles: the CIO's technology portfolio, cost taxonomy, operating model, enterprise architecture governance, rationalization and the evidence on digital transformation; the CTO's architecture decisions and ADRs, build-buy-partner, platforms, technical debt portfolios and team design; engineering productivity measurement (DORA, SPACE, DevEx) with anti-gaming safeguards; enterprise AI strategy, cost and governance handoffs; and boards, technology risk, vendor concentration, talent and the first 100 days.
About 15 hours · quiz of 14 questions · assignment with rubric
Learning objectives
- Create a technology portfolio map with a cost taxonomy and a sequenced rationalization plan, and justify allocation driver choices (assessed: Lesson 01 checks and lab, quiz q1-q3, assignment Part A).
- Evaluate digital transformation claims against the research and its critiques, including the productivity J-curve (assessed: Lesson 01 check c3, quiz q3).
- Create an architecture decision record and a weighted build-buy-partner analysis with sensitivity testing for an AI hiring platform (assessed: Lesson 02 checks and lab, quiz q4-q6, assignment Part B).
- Design an engineering metrics dashboard using DORA and SPACE measures with uncertainty estimates and anti-gaming safeguards, and critique its use as people data (assessed: Lesson 03 checks and lab, quiz q7-q9, assignment Part C).
- Analyze an enterprise AI strategy for model portfolio, unit cost, evidence on productivity and the governance handoff between CIO/CTO, CDO or CAIO, legal and HR (assessed: Lesson 03 checks c4-c5, quiz q10-q11).
- Create a 100-day plan with a board technology risk report, concentration analysis and talent strategy grounded in selection and socialization research (assessed: Lesson 04 checks and lab, quiz q12-q14, assignment Part D).
- The CIO: IT as a business capability, portfolio and transformation
- The CTO: architecture decisions, build or buy, platforms and teams
- Engineering productivity, developer experience and AI at the top
- Boards, technology risk, talent and the first 100 days
Module 45 The Chief Data and AI Officer
An Executive add-on module on running data and AI at chief-officer level: the CDO and CAIO mandates and reporting lines (including OMB M-25-21 for federal agencies), data and AI strategy tied to value, data mesh versus centralized platforms, data governance at scale (DAMA-DMBOK, quality measurement, metadata, lineage, master data, data contracts, retention, people-data stewardship), the AI portfolio (intake, risk tiering, honest value measurement, model risk management, incidents, build versus buy, cost), and executive AI governance (ISO/IEC 42001, NIST AI RMF and AI 600-1, the EU AI Act after the 2026 Digital Omnibus, Colorado, RACI, board reporting and workforce change).
About 16 hours · quiz of 14 questions · assignment with rubric
Learning objectives
- Create a one-page data and AI strategy that links business goals to capabilities, data dependencies, initiatives, risk tiers and measures, and justify an organizational structure for data (assessed: Lesson 01 checks and lab, quiz q1-q3, assignment Part A).
- Evaluate an officer mandate and reporting line against the federal OMB M-25-21 model and the principle of independent challenge (assessed: Lesson 01 checks, quiz q2, assignment Part A).
- Design data governance for people data, including critical data elements, quality metrics with sampled accuracy estimates, a data contract and a retention entry (assessed: Lesson 02 checks, quiz q4-q6, assignment Part B).
- Create a use-case intake and gate-then-score risk-tiering rubric and analyze inter-rater disagreement in its use (assessed: Lesson 03 checks and Lab 2, quiz q7-q8, assignment Part C).
- Design an AI value measurement plan with a counterfactual, power estimate and error costs, and evaluate vendor value claims (assessed: Lesson 03 checks and Lab 3, quiz q9-q10, assignment Part C).
- Create an AI governance charter, RACI and board reporting pack, and evaluate frameworks and legal obligations, including the EU AI Act as amended in 2026 (assessed: Lesson 04 checks and lab, quiz q11-q14, assignment Part D).
- The Chief Data and AI Officer role
- Data governance at scale
- AI portfolio, value and model risk
- Responsible AI governance and the board
Module 46 The Chief Risk Officer
Executive add-on: enterprise risk management at Chief Risk Officer level. COSO ERM 2017, ISO 31000:2018 and the Three Lines Model; risk taxonomies, appetite frameworks and CRO independence; why heat maps mislead and how loss distributions, Monte Carlo simulation, Value at Risk and Expected Shortfall aggregate dependent cyber, AI, legal and people risks; model, third-party, concentration, culture and employment-practices risk; operational resilience; and working with the board risk committee and regulators under deep uncertainty.
About 15 hours · quiz of 12 questions · assignment with rubric
Learning objectives
- Create a risk taxonomy, risk appetite framework and CRO charter for an HR-tech company, and evaluate the taxonomy's reliability with inter-rater agreement (assessed: Lesson 01 checks and lab, quiz q1-q3, assignment Part A).
- Evaluate the flaws of risk matrices and replace a heat map with a quantified Monte Carlo view of dependent risks, reporting Value at Risk and Expected Shortfall against appetite (assessed: Lesson 02 checks and lab, quiz q4-q7, assignment Part B).
- Analyze how model, third-party, concentration, culture and employment-practices risks combine, and design and run a combined cyber-AI-people stress scenario with a reverse stress test (assessed: Lesson 03 checks and lab, quiz q8-q10, assignment Part C).
- Create a board risk committee charter and quarterly CRO report that asks for specific decisions, shows uncertainty in numbers, keeps an independent view and applies debiasing structures (assessed: Lesson 04 checks and lab, quiz q11-q12, assignment Part D).
- Enterprise risk management and the CRO mandate
- Measuring and aggregating enterprise risk
- Integrating cyber, AI and people risk
- The CRO with the board and regulators
Module 47 The Boardroom and Executive Presence
The final module of the Executive add-on covers what every executive shares: corporate governance and the board's duties (care, loyalty and Caremark oversight, applied to cyber and AI), SEC disclosure of board risk oversight, serving on corporate, nonprofit and advisory boards (independence, D&O insurance and other protections, the board skills matrix), what research says and does not say about executive presence, influence, crisis communication, derailment and tone at the top, and evidence-based executive assessment, succession and onboarding, with the I-O psychology consultant's role in boardroom decisions.
About 15 hours · quiz of 14 questions · assignment with rubric
Learning objectives
- Analyze a company's board oversight of cyber and AI risk against the Caremark line of cases and Regulation S-K Items 106(c) and 407(h), and create a board memo and 10-minute presentation outline on AI risk (assessed: Lesson 01 checks and lab, quiz q1-q4, assignment Part A).
- Evaluate a board opportunity for independence, conflicts and director protections, and create a task-based board skills matrix and justified director profile (assessed: Lesson 02 checks and lab, quiz q5-q7, assignment Part B).
- Evaluate claims about executive presence, influence, crisis communication and derailment against the research evidence, and create a personal board-readiness plan built on observable behaviors (assessed: Lesson 03 checks and lab, quiz q8-q10, assignment Part C).
- Design an executive assessment, scoring rubric, succession and onboarding plan for a CISO or CAIO role, and justify its validity, reliability and fairness from the selection research (assessed: Lesson 04 checks and lab, quiz q11-q14, assignment Part D).
- Corporate governance and board oversight of cyber and AI risk
- Serving on boards: paths, duties, protections and the skills matrix
- Executive presence, influence and derailment: what the evidence says
- Executive assessment and succession: the I-O consultant in the boardroom